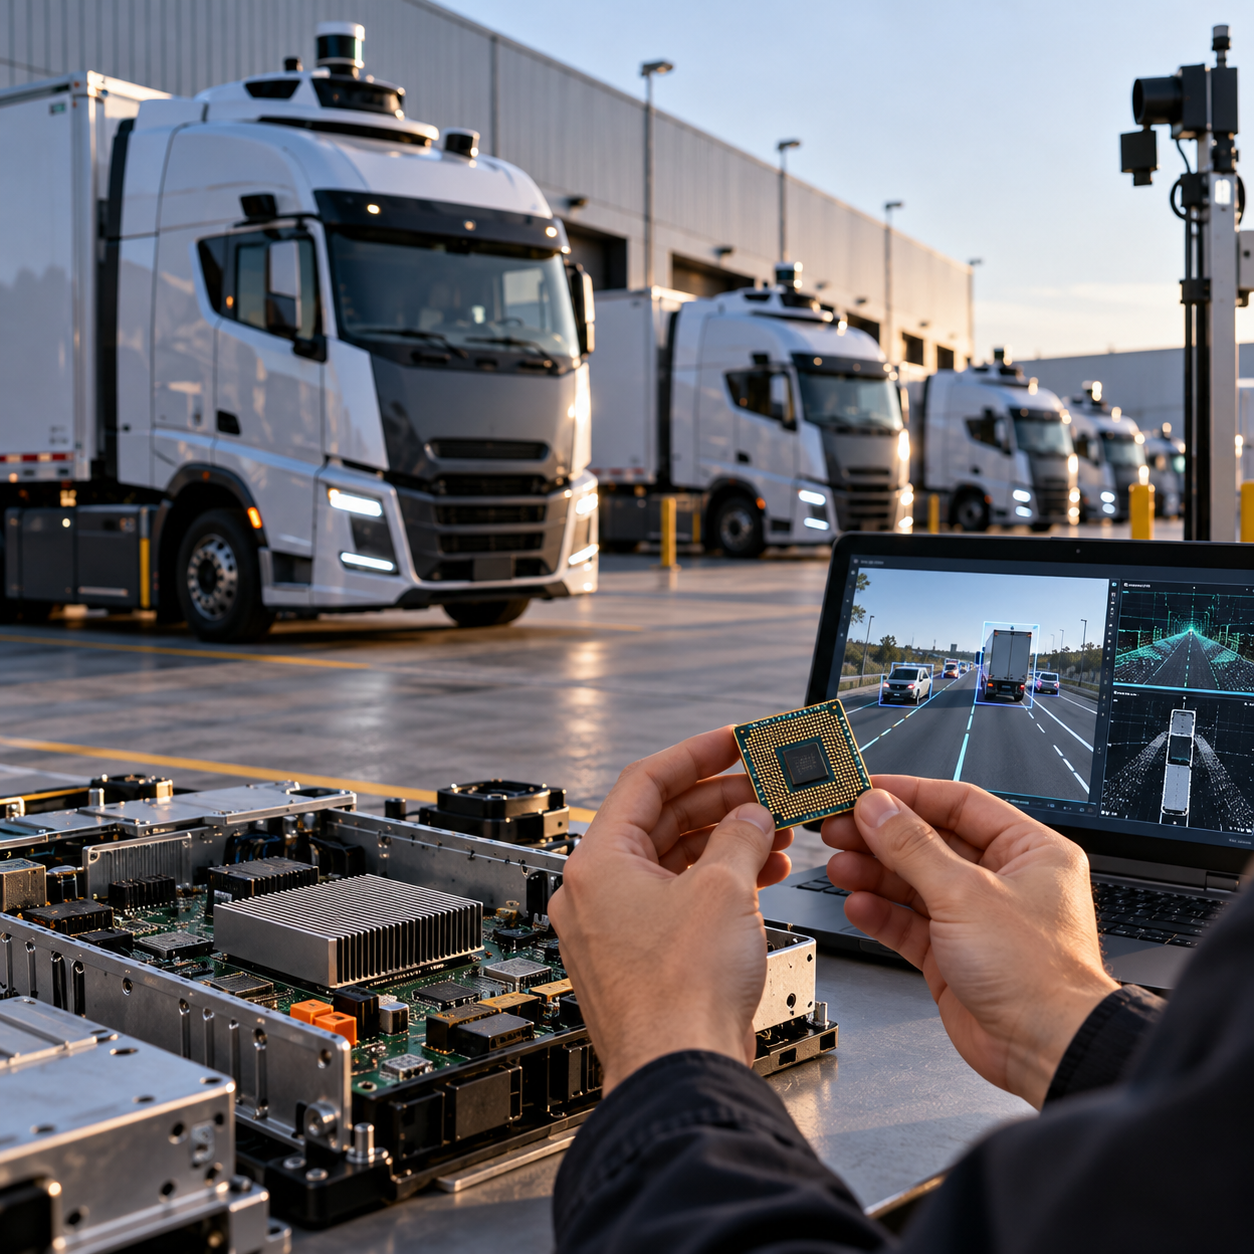
TechCrunch’s reporting on the custom chip supporting Waymo’s robotaxi ambitions highlights a consequential form of vertical integration: designing computing hardware around a specialized autonomous-driving workload instead of relying entirely on merchant silicon. For operators of robotaxis and other compute-intensive physical systems, the relevant lesson is not simply that custom chips can be faster. The real question is whether control over silicon can improve fleet economics and deployment reliability enough to justify years of engineering, validation, and supply-chain responsibility.
That threshold is high. An off-the-shelf platform spreads chip-development costs across many customers and offers mature tools, frequent upgrades, and relatively flexible sourcing. Custom silicon can remove unnecessary features, target critical workloads, and reduce dependence on a supplier’s product roadmap. Yet it also converts a procurement decision into a long-lived operating commitment. The choice therefore depends on workload stability, scale, power constraints, safety requirements, and the organization’s ability to manage hardware throughout its life cycle.
What Waymo’s strategy reveals about the operator decision
The cited TechCrunch report presents Waymo’s custom-chip work in the context of its robotaxi ambitions. That context matters: autonomous vehicles must process sensor data under tight latency, power, thermal, and safety constraints, while the operator must deploy and maintain the same computing architecture across a fleet. Hardware is not an isolated component; it affects vehicle packaging, cooling, energy use, software behavior, validation, maintenance, and expansion capacity.
Waymo should not be treated as proof that every autonomous-mobility company needs its own chip. It is better understood as evidence that a scaled, specialized operator may regard computing architecture as strategically important enough to internalize. The applicability of that choice depends on whether another operator has comparable workload specificity, deployment repetition, and engineering depth.
Custom silicon becomes more credible when the production workload is both important and stable. If perception, inference, sensor processing, or another recurring function has a predictable computational profile, engineers can optimize hardware for what the fleet actually runs. If models, sensors, and system architecture are still changing rapidly, committing them to silicon risks freezing yesterday’s assumptions into tomorrow’s vehicles.
The economic case extends beyond chip price
A responsible comparison should calculate cost at the deployed-system level rather than compare component prices. A specialized chip could improve economics through lower power demand, reduced cooling requirements, fewer supporting components, or better utilization of installed compute. In an electric autonomous vehicle, power efficiency may also affect operational availability and vehicle-level energy consumption. These gains must be measured in the complete platform, not assumed from theoretical processor efficiency.
Scale determines whether recurring benefits can absorb the substantial non-recurring burden. Custom hardware requires architecture work, design tools, verification, software enablement, prototypes, manufacturing preparation, and repeated safety and reliability testing. It also demands engineering capacity after launch. Defects, packaging changes, manufacturing transitions, security updates, and component obsolescence do not disappear once the design is complete.
Operators should model several scenarios without relying on a single fleet forecast. The analysis should ask how economics change if deployment is delayed, vehicle volume is lower than planned, a redesign becomes necessary, or the chip remains in service longer than expected. A custom design that pays off only under an aggressive expansion case is not merely a technology investment; it is a concentrated bet on fleet growth.
Off-the-shelf systems retain a strong advantage for smaller fleets. Their development costs are shared across a supplier’s customer base, and operators can often reach deployment sooner with established development environments. Even if a merchant processor includes unused capability or carries a supplier margin, that premium may be far cheaper than funding an internal silicon organization.
Performance must be translated into fleet outcomes
“Higher performance” is too vague for a build decision. Operators need workload-specific targets: worst-case latency, throughput under representative sensor loads, deterministic behavior, memory movement, power draw, thermal limits, and performance after safety mechanisms are enabled. The proper benchmark is the production software stack under demanding operating conditions, not an isolated model demonstration.
The best custom-chip opportunities are usually persistent bottlenecks. If a workload repeatedly consumes disproportionate power or constrains system latency, specialized acceleration may create durable value. Conversely, optimization is risky when the bottleneck is likely to move because sensor configurations or model architectures are unsettled.
Software portability also deserves explicit valuation. A tightly coupled chip and software stack can improve efficiency, but it may make future model changes harder. Operators should identify which layers will remain programmable, what happens when workloads exceed design assumptions, and whether a fallback execution path exists. Flexibility has an operating value even when it appears inefficient on a benchmark.
Supply control can replace one dependency with several others
Reducing reliance on an external chip vendor’s product choices is a legitimate strategic objective. Merchant suppliers may change roadmaps, discontinue components, alter commercial terms, or prioritize larger markets. Owning the architecture can give a fleet operator more influence over feature priorities and product longevity.
However, designing a chip does not create full supply independence. The operator may still depend on fabrication, packaging, memory, design software, intellectual-property blocks, test capacity, and specialist engineering partners. Custom silicon can therefore exchange visible vendor lock-in for a more complex network of dependencies.
A supply-resilience plan should cover second-source possibilities, inventory strategy, geographic concentration, manufacturing lead times, and the feasibility of moving a design to another process or partner. Contracts should address long-term availability and change notification. The organization also needs a response if yields disappoint or a critical component becomes unavailable.
Upgrade cadence is another trade-off. Merchant platforms may deliver new capabilities more frequently, while a proprietary chip’s development cycle can be lengthy. Operators can mitigate this with a modular architecture: preserve programmability for changing workloads, separate stable acceleration functions from fast-moving ones, and avoid making the entire vehicle platform dependent on a single silicon revision.
Validation and safety are part of the product
For autonomous fleets, custom hardware must be assessed as part of the safety case. Verification must address not only nominal calculations but also timing faults, memory corruption, thermal stress, manufacturing variation, degradation, diagnostic coverage, and failure behavior. Evidence must connect hardware behavior to system-level risk controls.
Development timelines should consequently include requirements definition, design verification, prototype bring-up, software integration, vehicle testing, manufacturing qualification, and safety-assurance work. Discovering a defect late can delay an entire vehicle generation. An operator also needs configuration control so it knows which hardware, firmware, models, and safety evidence apply to every deployed vehicle.
This burden changes organizational requirements. A credible program needs clear authority across silicon, software, vehicle engineering, procurement, security, and safety. If those groups optimize independently, a technically impressive chip can still fail operationally through integration delays or unmanageable validation scope.
A build-versus-buy checklist for fleet operators
- Workload stability: Are the critical computations predictable enough to encode into hardware for several deployment cycles?
- Measurable constraint: Is there a demonstrated latency, power, thermal, packaging, or supply problem that merchant platforms cannot resolve adequately?
- Fleet scale: Can realistic deployment volume—not the most optimistic forecast—spread development and support costs?
- System economics: Does the model include cooling, energy, supporting components, software work, validation, inventory, and redesign risk?
- Time to deployment: Can the operation tolerate the custom program’s schedule, including qualification and potential rework?
- Software adaptability: Will future models and sensor configurations fit, and which functions remain programmable?
- Safety assurance: Can the operator produce and maintain evidence for hardware faults, updates, and field changes?
- Supply resilience: Are fabrication, packaging, tools, IP, memory, and testing dependencies mapped and mitigated?
- Life-cycle ownership: Is there funding and expertise for security, obsolescence, manufacturing changes, and failure analysis?
- Exit option: Can the software or vehicle architecture return to merchant hardware if volume, strategy, or technology changes?
For many operators, the answer will be a hybrid architecture rather than complete vertical integration: custom acceleration for stable, differentiating workloads, paired with programmable merchant components for functions that evolve quickly. Before commissioning silicon, benchmark the production workload, quantify the fleet-level constraint, compare hybrid alternatives, and stress-test the business case against delays and lower volume. Waymo’s reported strategy illustrates why custom chips can align with robotaxi scale and specialization; it does not remove the need for each operator to prove that owning the hardware will improve the operation rather than merely deepen its technical commitments.