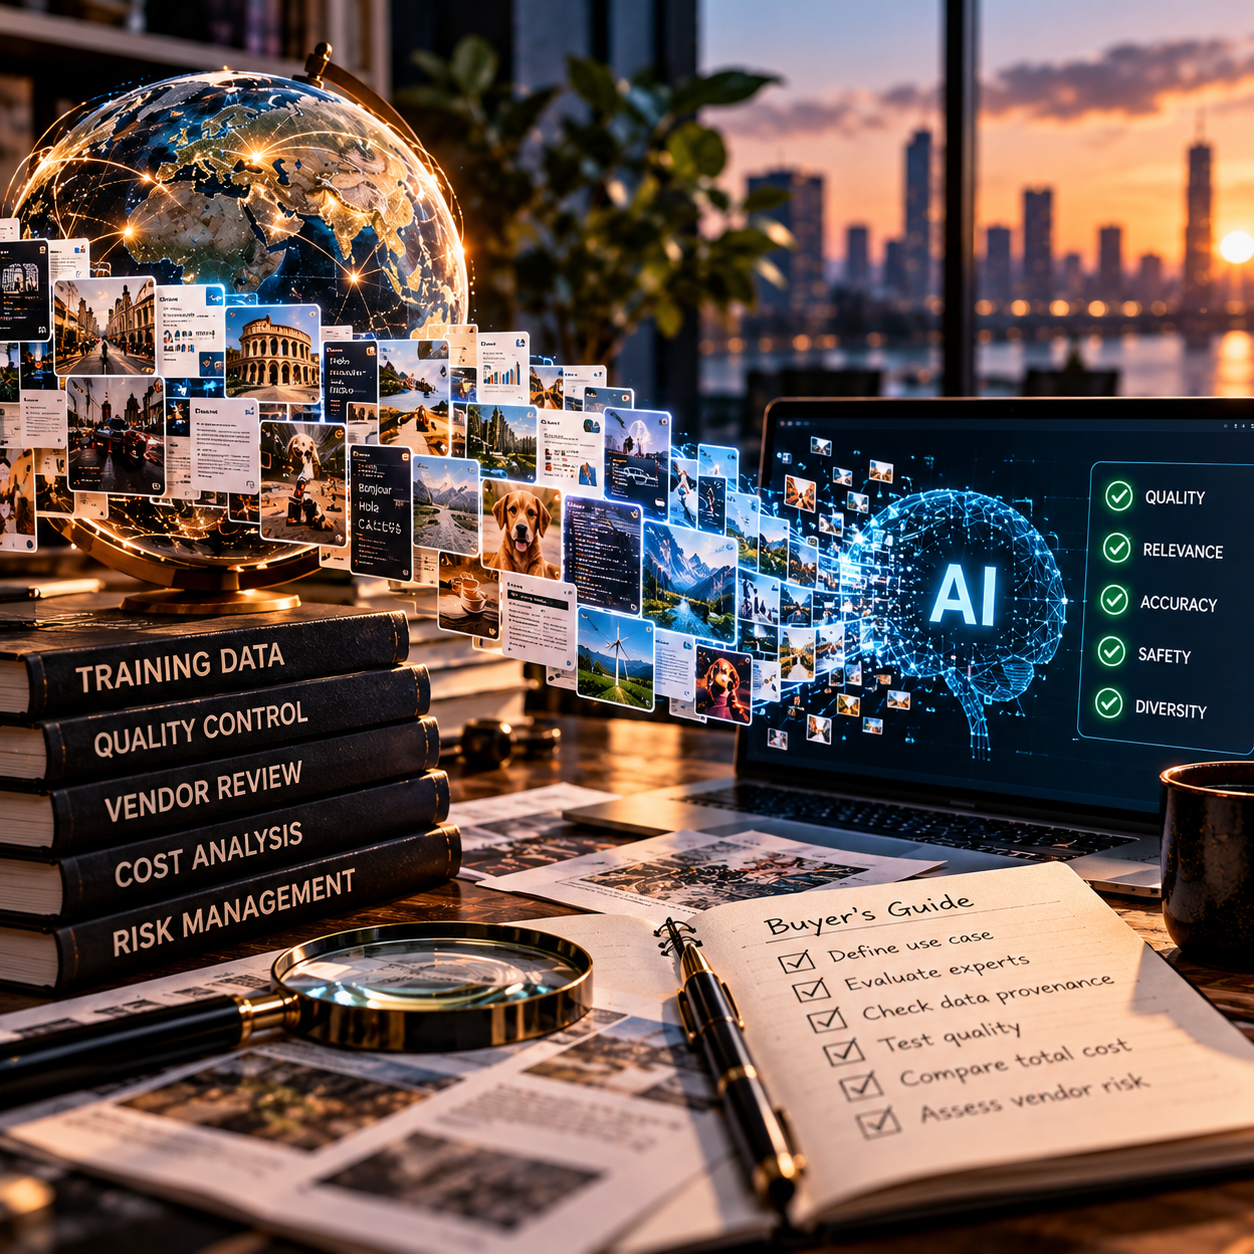
Micro1’s reported $500 million gross run rate, as covered by TechCrunch, is best read as a signal of strong demand for human-generated training data and reinforcement-learning services—not as proof of audited or recognized revenue. For AI teams, the more important question is what that demand means for procurement. A vendor can grow quickly while still being the wrong fit for a particular model, domain, risk profile, or budget.
Buying training data is not comparable to purchasing a static software license. The deliverable depends on workforce selection, task design, consent, quality control, security, and feedback loops with model developers. Buyers therefore need to evaluate both the data and the operating system that produces it.
Why AI Developers Still Pay for Human Data
Foundation models learn broad patterns from large corpora, but many production use cases require behavior that raw pretraining data does not reliably teach. Human contributors can create demonstrations, compare alternative outputs, identify policy violations, solve domain-specific problems, critique reasoning, or score responses against a rubric. These signals can then support supervised fine-tuning, preference optimization, evaluation, and reinforcement-learning workflows.
The need becomes more demanding as models move into medicine, law, finance, cybersecurity, science, and complex software engineering. A fluent generalist cannot necessarily judge whether an answer is clinically safe, legally sound, or technically correct. Procurement consequently shifts from buying annotation volume to buying verified judgment.
Demand alone should not determine vendor selection. The relevant capability is repeatable production of the right signal for a defined model objective. Buyers should begin with the failure mode they want to reduce: hallucination, unsafe advice, weak tool use, poor coding accuracy, unreliable multilingual performance, or another measurable deficiency. Without that definition, more labels may produce more cost rather than a better model.
Separate Vendor Momentum From Commercial Reality
TechCrunch reports Micro1’s gross run rate, but buyers should not interpret a run-rate figure as equivalent to audited annual revenue. Run rate generally annualizes performance over a shorter period, while the word “gross” may indicate that payments or other pass-through amounts have not been deducted. Recognized revenue depends on accounting treatment, delivery, contract terms, and the distinction between gross and net reporting.
This distinction matters operationally. Rapid headline growth may indicate market traction and access to workers, yet it does not establish profitability, customer retention, delivery consistency, or financial resilience. During diligence, ask the vendor to define the metric precisely: the measurement period, whether it annualizes bookings, billings, transaction volume, or revenue, and which workforce costs are included.
Vendor momentum can still be useful evidence. Scale may support faster recruitment, broader specialist pools, and investment in quality systems. It may also create risks: rushed onboarding, inconsistent review, dependence on a few large customers, or pressure to prioritize volume. Buyers should assess performance on their own workload rather than infer quality from growth.
Test Quality and Specialist Coverage at the Task Level
A credible proposal should explain who will perform the work and how the vendor verifies them. For domain experts, request evidence of identity checks, credentials, relevant experience, language proficiency, and task-specific qualification. Verification should match the risk. A university email address may be insufficient proof of expertise; a professional license alone may not demonstrate competence in a narrow specialty.
Examine how the vendor converts a broad expert pool into a qualified project team. Ask about screening tests, calibration rounds, minimum passing scores, ongoing monitoring, reviewer escalation, and procedures for removing poor performers. If subcontractors or multiple labor platforms are involved, determine whether the same controls apply throughout the chain.
Quality assurance should extend beyond inter-annotator agreement. Agreement can be misleading when a rubric is ambiguous or several contributors share the same misconception. Depending on the task, useful controls include expert adjudication, hidden gold-standard items, duplicate assignments, rationale review, anomaly detection, and analysis by worker cohort. Buyers should also require version control for instructions and a record of which rubric produced each label.
Turnaround commitments need similar scrutiny. Ask for capacity by specialty and language, not merely total worker count. Establish service levels for initial delivery, corrections, adjudication, and replacement of rejected items. A fast first batch has little value if defect resolution takes weeks.
Trace Provenance, Consent, Privacy, and Security
Every dataset should have a defensible lineage. Buyers need to know whether content was created for the project, licensed, collected from public sources, derived from customer material, or generated with model assistance. Provenance records should connect each item to its source category, contributor terms, transformations, quality checks, and permitted uses.
Consent must cover the intended downstream activity. A contributor’s agreement to complete a task does not automatically resolve rights to reuse their submission, voice, likeness, personal information, or professional work product for model development. Contracts should allocate intellectual-property rights, prohibit unauthorized scraping or substitution, and require disclosure of synthetic or externally sourced content.
Privacy diligence should map what enters the vendor environment: prompts, model outputs, customer documents, personal data, source code, or regulated information. Ask about data minimization, regional processing, retention periods, deletion verification, encryption, access controls, incident response, audit logs, and subprocessors. Confirm whether contributors can download material or access it on unmanaged devices.
Security questionnaires are not enough for sensitive projects. Require evidence supporting the answers, define notification deadlines, and reserve audit or assessment rights. Segment high-risk work where possible, use redacted examples during qualification, and avoid sending production secrets until controls have been tested.
Compare Pricing Through Usable Output, Not Headline Rates
Training-data prices may be quoted per task, item, hour, accepted label, expert session, or project. None is meaningful without the denominator. A low per-item rate can become expensive after rework, adjudication, management overhead, and discarded records.
Calculate cost per accepted, usable unit. Include task design, recruiting, qualification, contributor pay, platform fees, quality review, corrections, secure-environment charges, project management, and internal engineering time. For specialist tasks, also consider scarcity: tighter credentials can raise price and extend lead times but may reduce costly label noise.
Contracts should specify acceptance criteria, sampling methods, remediation, ownership, and treatment of failed batches. Volume commitments can lower unit prices, but they create lock-in before quality is proven. Prefer staged commitments, transparent rate cards, and the ability to export data, metadata, rubrics, and audit history in usable formats.
Vendor concentration deserves explicit limits. A single provider can simplify coordination, yet an outage, policy change, security event, or labor shortage could interrupt model development. Maintain a fallback supplier or an internal capability for critical evaluation sets, and ensure that task specifications are portable.
Run a Pilot That Measures Model Impact
A pilot should test an end-to-end hypothesis, not merely whether the vendor can deliver a file. Use a representative task slice containing normal cases, edge cases, ambiguous items, and relevant risk categories. Keep a blinded holdout set so that supplier performance is not judged only on examples used during calibration.
Track operational metrics such as qualification pass rate, agreement, expert-adjudicated accuracy, rejection and rework rates, delivery latency, cost per accepted item, and error distribution by domain or worker cohort. Then test the data in the intended pipeline. Compare the resulting model or policy with a baseline using task-specific performance, safety, robustness, and regression metrics.
Before scaling, buyers should be able to answer six questions: Did the data improve the target behavior? Were gains meaningful on an independent evaluation set? Did performance deteriorate elsewhere? Can the vendor reproduce quality at higher volume? Is provenance complete enough for future audits? Does the all-in cost justify the measured improvement?
The current boom expands buyer choice, but supplier growth is not a substitute for evidence. Define the model problem, verify the people and provenance behind the labels, test security controls, normalize costs around accepted output, and release volume only after a controlled pilot demonstrates measurable value.